The blog · LLM inference
What happens
after you hit
Enter.
LLM inference explained simply, and measured for real: tokens, prefill, decode, the KV cache, batching and more. Every claim comes with code you can run and time yourself.
“Why is the sky blue?”
01 / Latest
Latest
articles.
Short, friendly on-ramps to how production LLMs really serve answers. Start anywhere, or read the series in order.
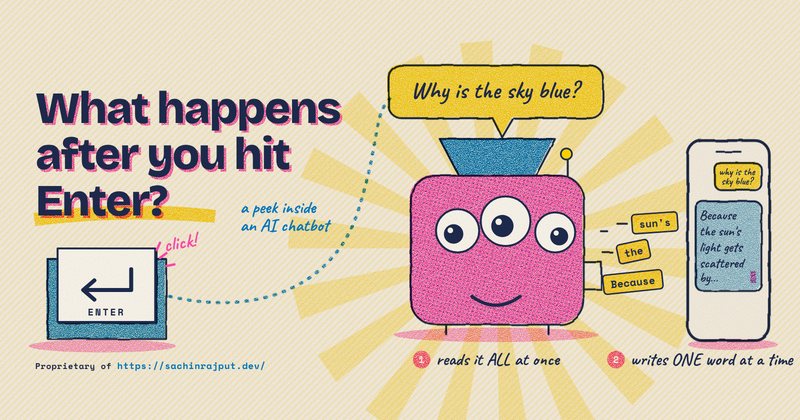
One Request, End to End: Tokenize, Prefill, Decode, Stream
What really happens in the second after you ask a chatbot a question? A trip through the Word Factory, explained simply, with a tiny engine you can run and time yourself.
Up next · Part 2
A Forward Pass for One Token: Where the FLOPs Go
Follow along so you don’t miss it.
02 / Series
Inference Foundations
1 of 10 published.
How AI chatbots actually answer you, explained simply and measured for real. Short, friendly on-ramps to LLM inference: tokens, prefill, decode, the KV cache, batching and more.
- One Request, End to End: Tokenize, Prefill, Decode, Stream14 min read
- A Forward Pass for One Token: Where the FLOPs GoComing soon
- Prefill vs Decode: Two Phases, Two BottlenecksComing soon
- The Roofline Model for LLM InferenceComing soon
- The KV Cache From ScratchComing soon
- How Much GPU Memory Do I Need?Coming soon
- Continuous Batching and PagedAttentionComing soon
- Speculative Decoding BasicsComing soon
- Tensor, Pipeline and Expert ParallelismComing soon
- Quantization Formats: FP16, BF16, FP8, INT8, INT4Coming soon
New article every few days
Get the next one
as it ships.
How AI models really answer you, explained simply and measured for real. I share every new part on LinkedIn first, and the RSS feed has the full text.